Weave automatically tracks and logs LLM calls made via the Cerebras Cloud SDK.
Traces
Tracking LLM calls is crucial for debugging and performance monitoring. Weave helps you do this by automatically capturing traces for the Cerebras Cloud SDK.
Here’s an example of how to use Weave with Cerebras:
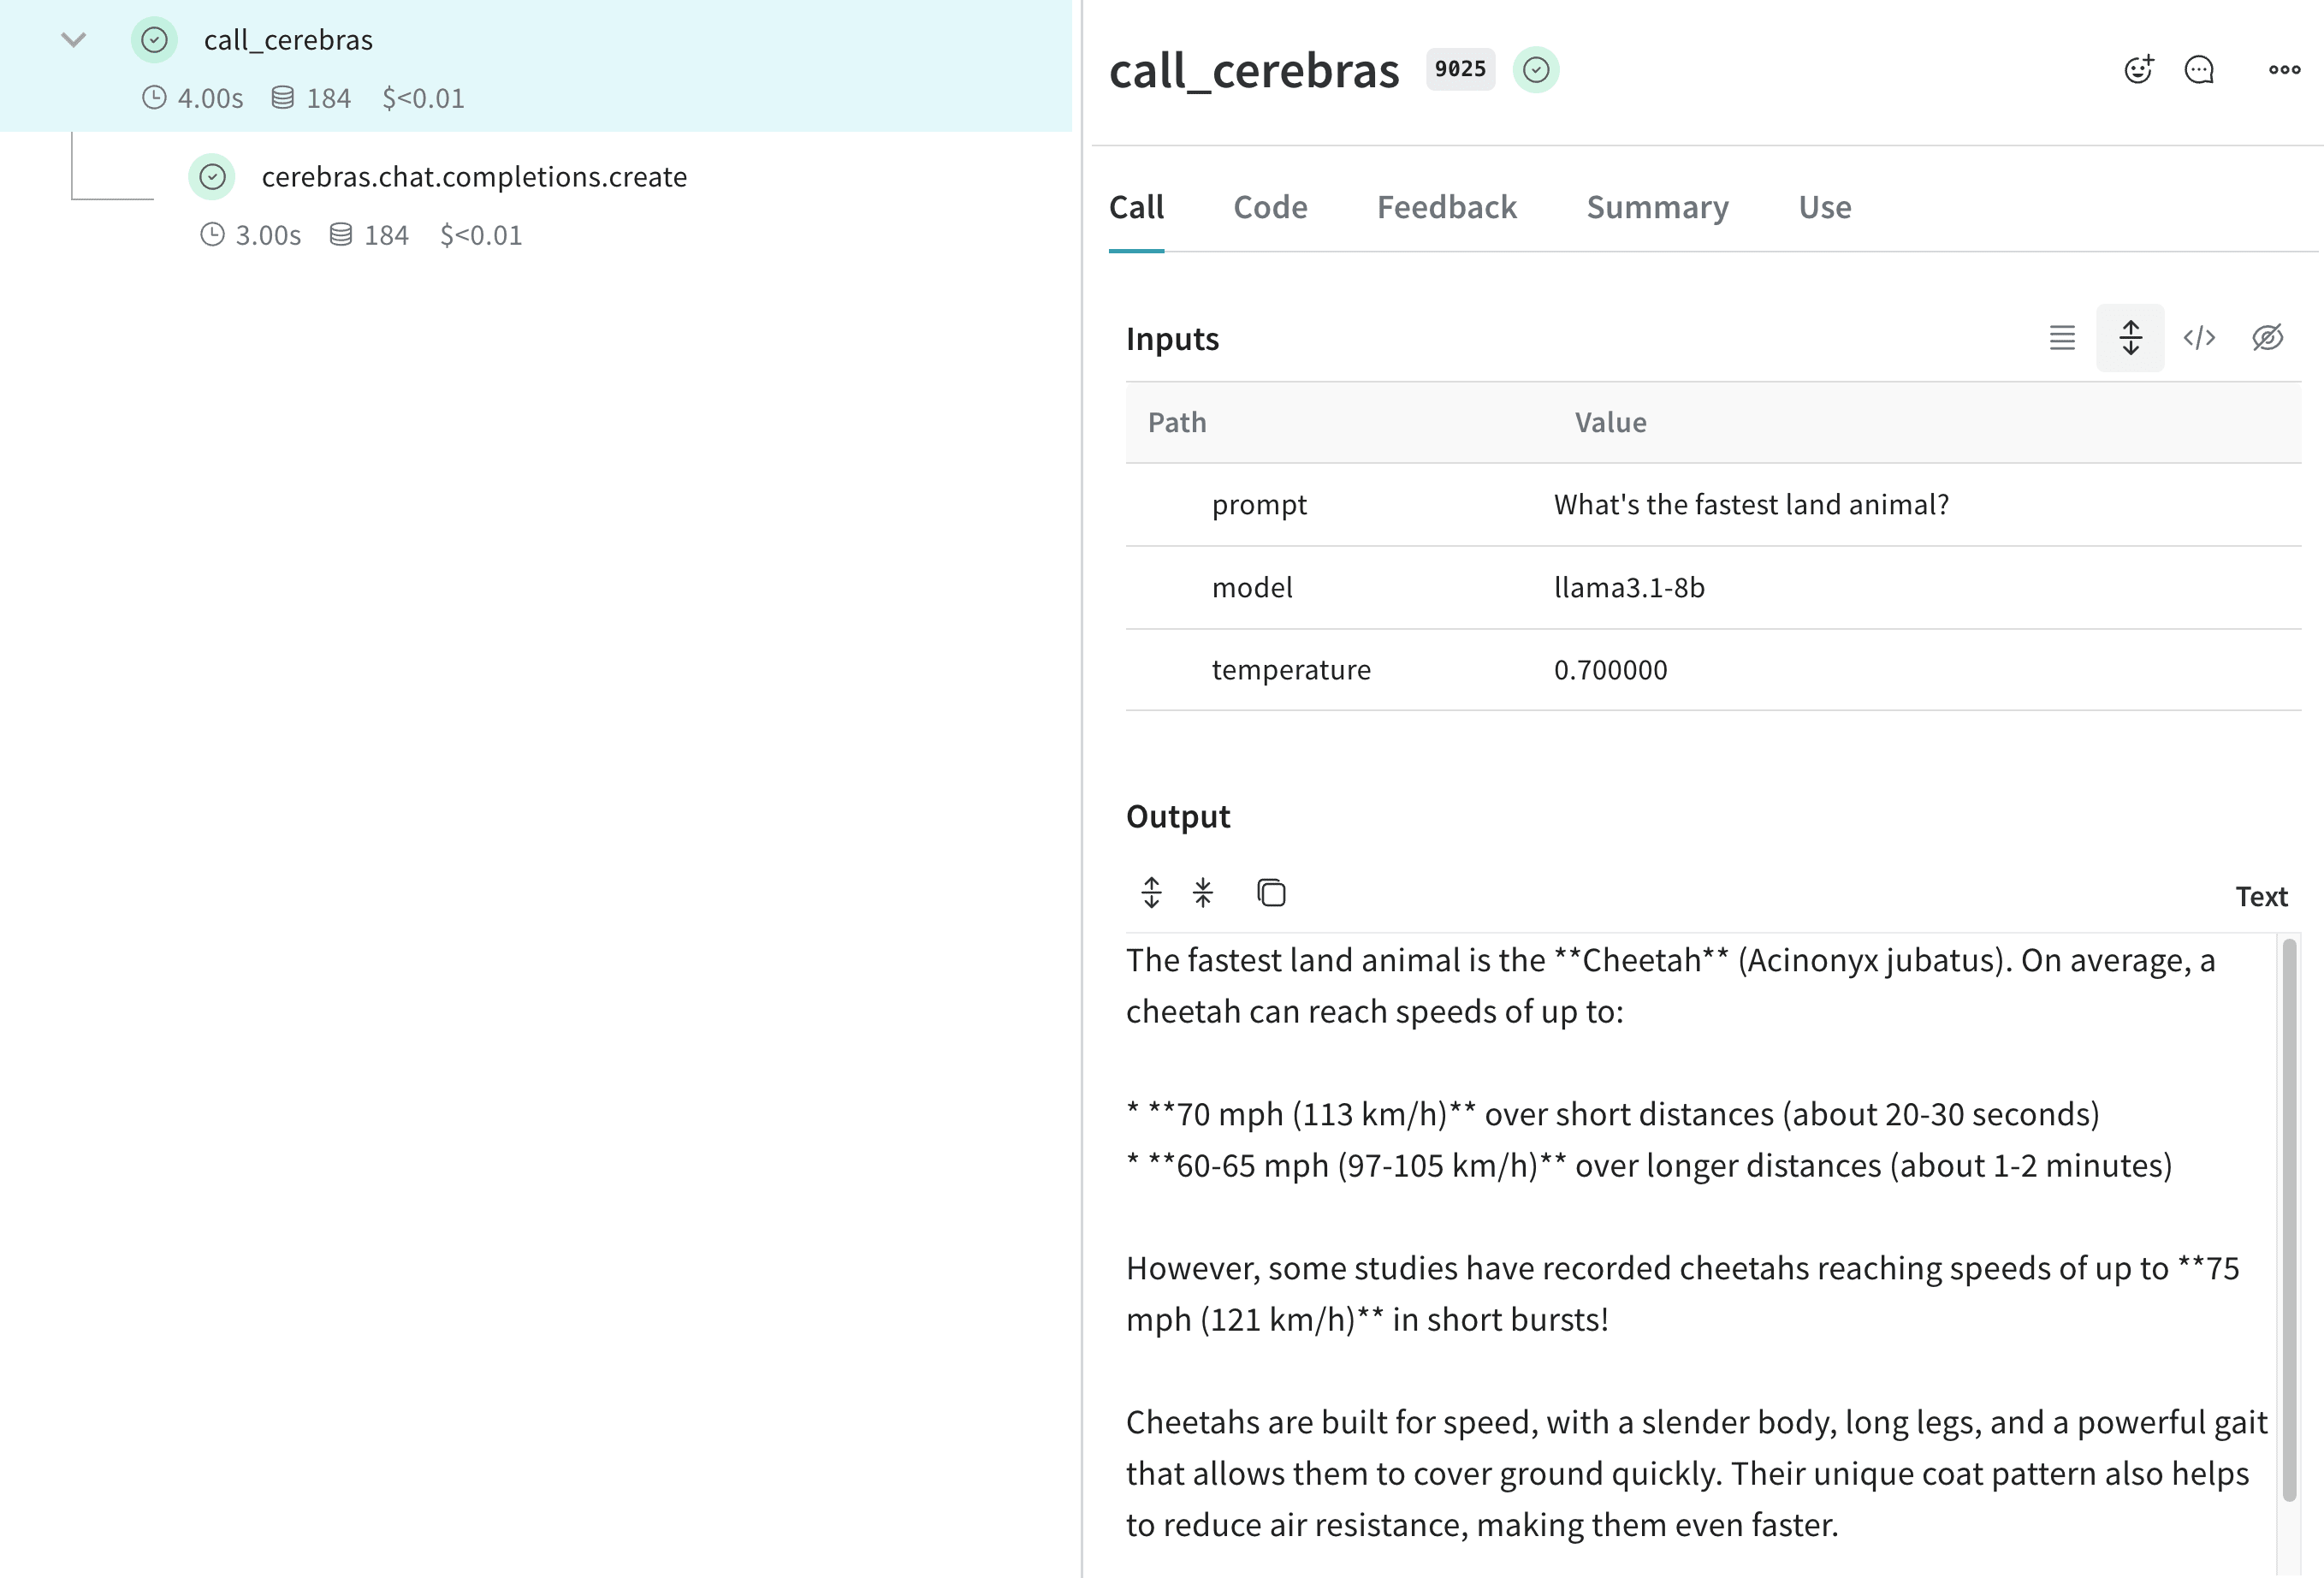
Weave now tracks and logs all LLM calls made through the Cerebras SDK. You can view the traces in the Weave web interface, including details like token usage and response time.
Wrap with your own ops
Weave Ops enhance reproducibility and traceability in your experiments by automatically versioning your code and capturing inputs and outputs. Here’s an example of how to use Weave Ops with the Cerebras SDK:
Create a Model for easier experimentation
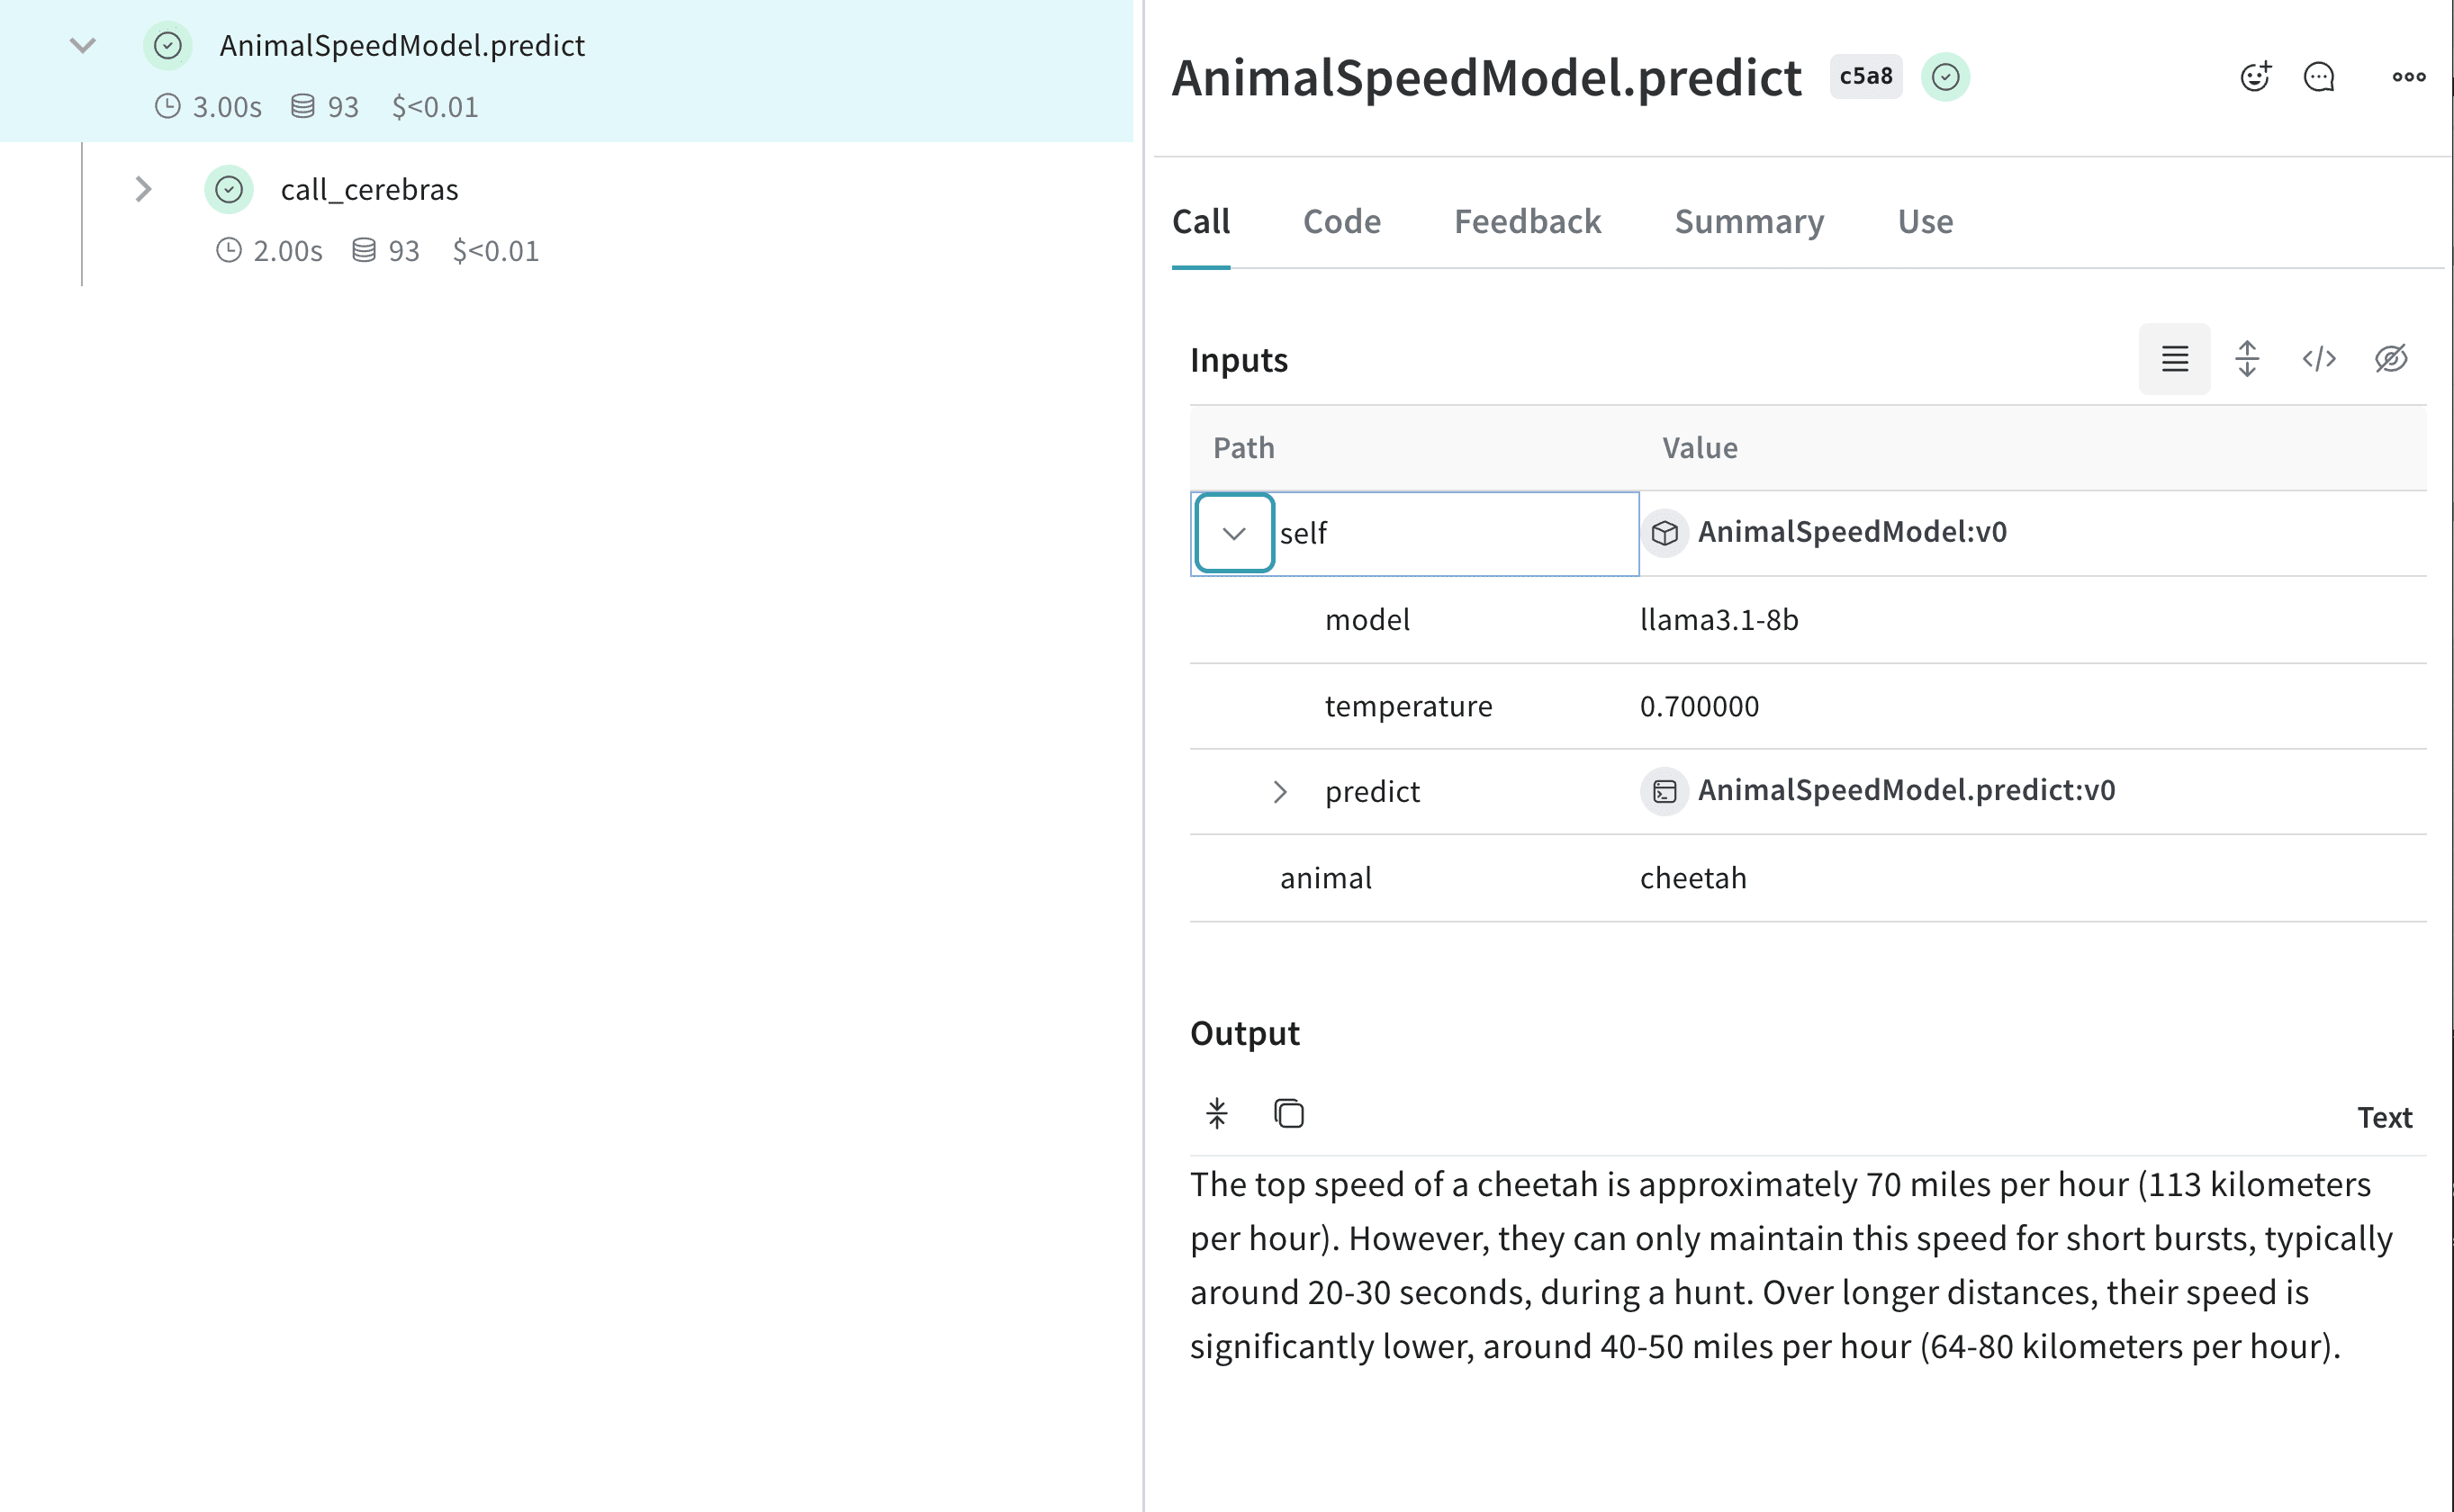
The Model class in Weave helps you organize and compare different iterations of your app. This is useful when experimenting with Cerebras models. Here’s an example:
With this setup, you can experiment with different models and parameters while tracking your Cerebras-powered inferences.
Last modified on September 30, 2026

