

For instructions about accessing CoreWeave Grafana dashboards, see Access and use CoreWeave Grafana dashboards.
Dashboard variables
To choose the deployment you want to inspect, set the variables at the top of the dashboard. Most panels follow the Deployment selection. For the exceptions, see Overview.
The dashboard also provides a vLLM Logs link that opens Explore with a log query already scoped to your current Deployment selection.
Panel rows
The dashboard groups its panels into five rows. The following sections describe each row.Overview
These panels summarize the health and throughput of the selected deployment. Start here to determine whether the deployment is serving traffic successfully. The RPS, Model Success Rate, Request Duration, Completed Request Rate, and First Response Duration panels measure requests at the gateway and filter by Model, Gateway, and Zone only. If more than one deployment serves the selected model through the selected gateway, these panels include all of them.Queue & Load Balancing
These panels show how requests move through the queue before a backend accepts them. Use them to distinguish a capacity shortfall from a load balancing failure.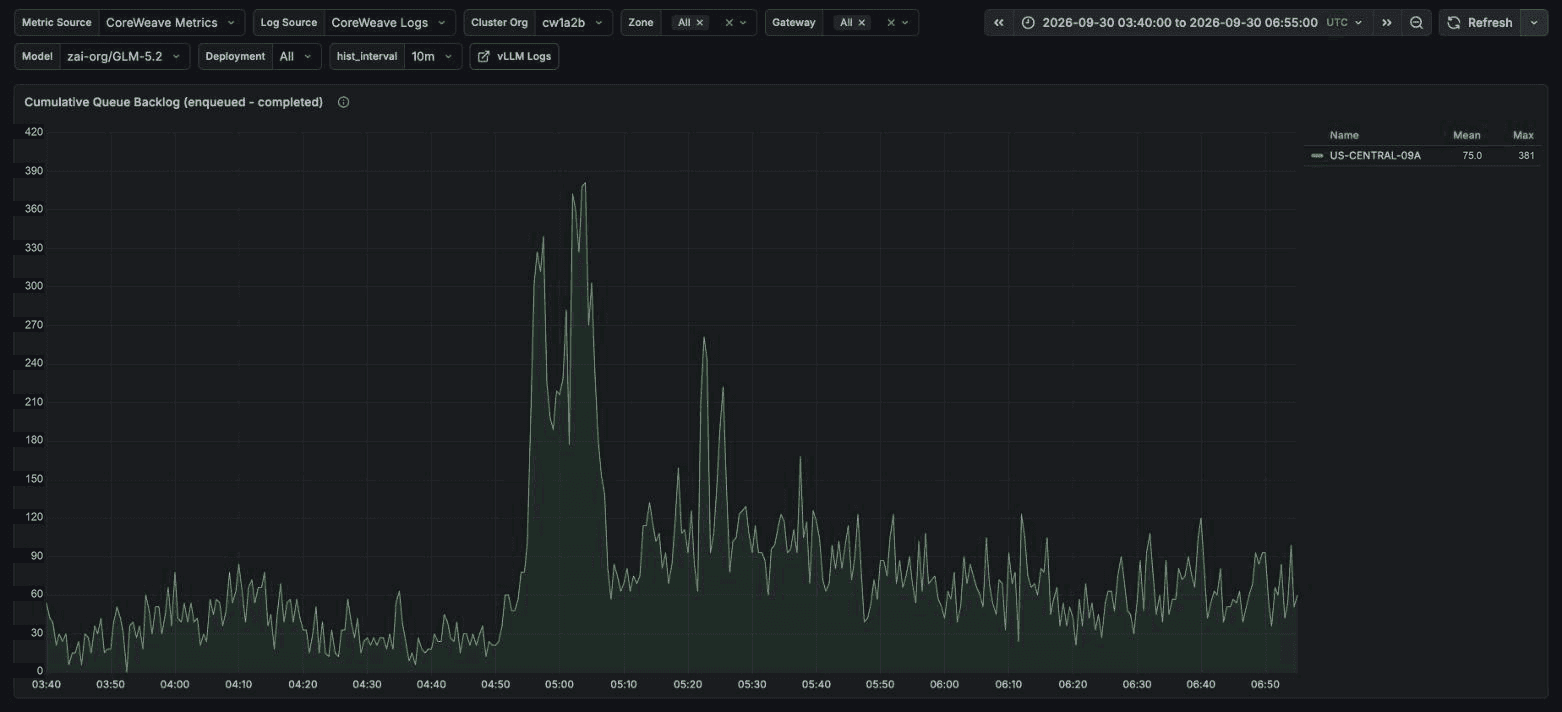
The Cumulative Queue Backlog panel for one model over about three hours. Just before 05:00, the backlog rises from under 60 to about 380 waiting requests, then falls back. The values are scaled example data.
VLLM
These panels report metrics published by the vLLM inference runtime. They break request latency into its runtime stages and report token counts per request, so you can find which stage dominates end-to-end latency.Scaling
These panels show how the deployment’s replica count responds to load. You can read them alongside Scaling, which describes the autoscaling behavior they reflect.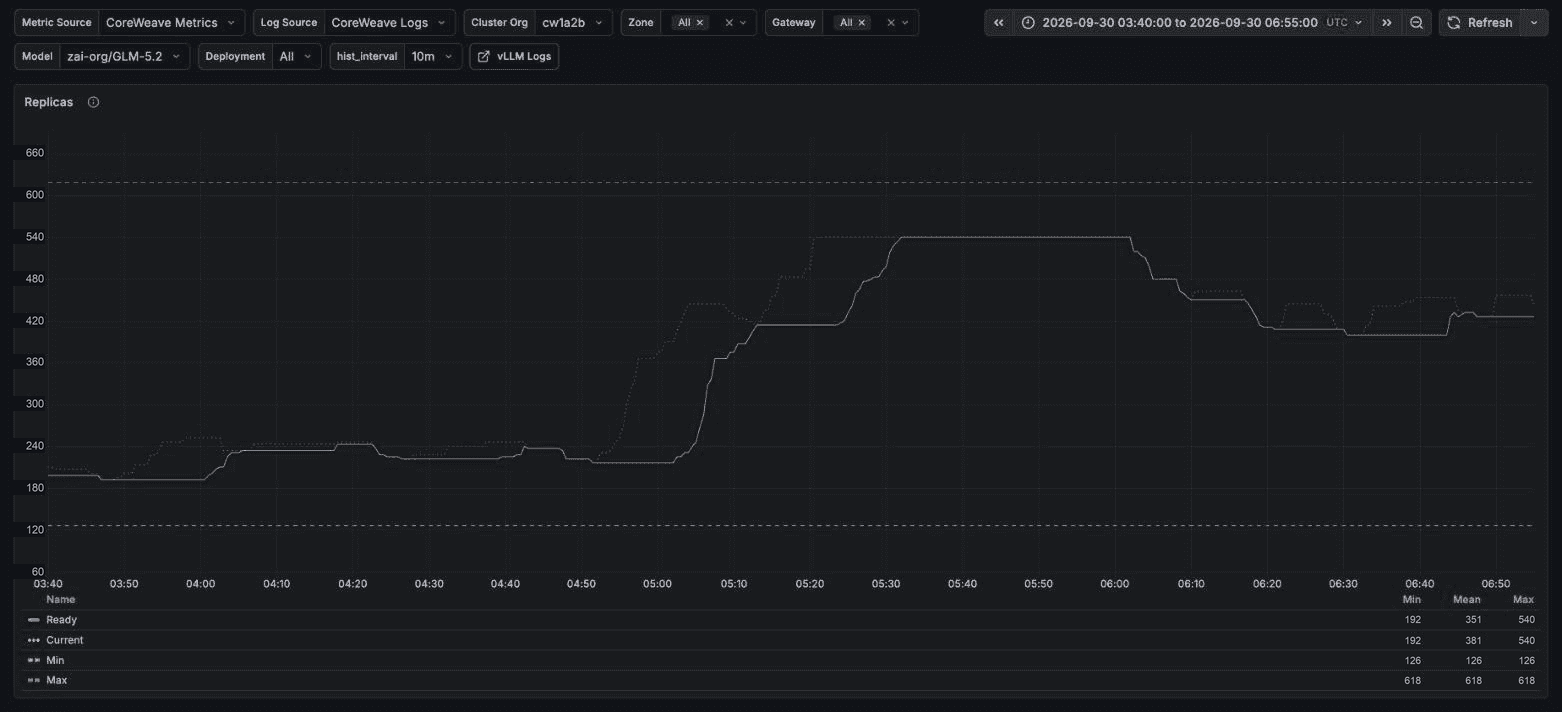
The Replicas panel for the same model and time range. As the backlog grows, the autoscaler adds replicas within the configured minimum and maximum, then removes replicas after demand falls. The values are scaled example data.
Per Pod
Each replica of a deployment runs as one or more Kubernetes Pods. These panels break the selected deployment out by Pod, so you can distinguish an evenly loaded deployment from one where a single Pod is saturated.The Per Pod panels cover only the Pods belonging to your own deployments. The dashboard doesn’t include Node-level metrics or a Pod-to-Node mapping.
See also
- Dedicated Inference: Learn about deployments, gateways, and the observability role requirement.
- Scaling: Configure the autoscaling behavior shown in the Scaling row.
- Speculative decoding: Configure the feature measured by the Speculative Decoding panel.