> ## Documentation Index
> Fetch the complete documentation index at: https://docs.coreweave.com/llms.txt
> Use this file to discover all available pages before exploring further.
# NVIDIA NIM
> Use Weave to trace and log LLM calls made through the ChatNVIDIA library
`weave.init()`을 호출하면 Weave가 [ChatNVIDIA](https://python.langchain.com/docs/integrations/chat/nvidia_ai_endpoints/) 라이브러리로 수행한 LLM Call을 자동으로 추적하고 로깅합니다. 이 가이드에서는 ChatNVIDIA를 사용하는 Python 개발자를 위해 트레이스를 캡처하고, 직접 작성한 함수를 Op으로 래핑하고, Weave의 `Model` 클래스로 실험을 체계적으로 관리하는 방법을 설명합니다. 이를 활용하면 LLM 애플리케이션을 더 효율적으로 디버깅하고, 반복 개선하고, 비교할 수 있습니다.
최신 튜토리얼은 [Weights & Biases on NVIDIA](https://wandb.ai/site/partners/nvidia)에서 확인하세요.
트레이싱
개발 단계와 프로덕션 환경 모두에서 LLM 애플리케이션의 트레이스를 중앙 데이터베이스에 저장해 두면 문제를 디버깅하기 쉽고, 애플리케이션을 개선하는 과정에서 평가에 활용할 까다로운 예시로 데이터셋을 구축할 수 있습니다. 다음 섹션에서는 ChatNVIDIA Call의 자동 트레이싱을 활성화하는 방법을 설명합니다.
Weave는 [ChatNVIDIA Python 라이브러리](https://python.langchain.com/docs/integrations/chat/nvidia_ai_endpoints/)의 트레이스를 자동으로 캡처할 수 있습니다.
원하는 프로젝트 이름을 지정하여 `weave.init([PROJECT-NAME])`을 호출하면 캡처가 시작됩니다.
```python lines {4} theme={"system"}
from langchain_nvidia_ai_endpoints import ChatNVIDIA
import weave
client = ChatNVIDIA(model="mistralai/mixtral-8x7b-instruct-v0.1", temperature=0.8, max_tokens=64, top_p=1)
weave.init('emoji-bot')
messages=[
{
"role": "system",
"content": "You are AGI. You will be provided with a message, and your task is to respond using emojis only."
}]
response = client.invoke(messages)
```
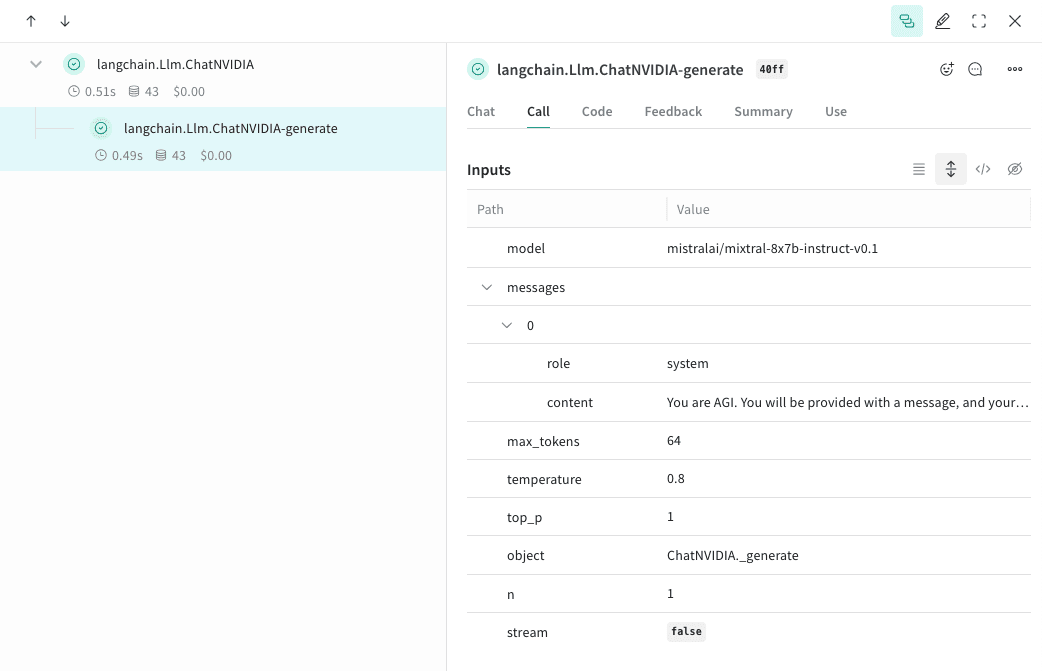
이 코드를 실행하면 Weave가 지정한 프로젝트에 ChatNVIDIA Call을 캡처하며, 해당 프로젝트에서 입력, 출력, 메타데이터를 확인할 수 있습니다.
```plaintext theme={"system"}
This feature is not available in TypeScript yet since this library is only in Python.
```
직접 작성한 Op 추적하기
함수를 `@weave.op`로 래핑하면 입력, 출력, 앱 로직이 캡처되기 시작하므로 앱에서 데이터가 어떻게 흐르는지 디버깅할 수 있습니다. Op를 깊게 중첩하여 추적하려는 함수의 트리를 구축할 수도 있습니다. 또한 자동 코드 버전 관리도 시작되므로, 실험하는 동안 Git에 아직 커밋하지 않은 임시 변경 사항까지 캡처됩니다.
[ChatNVIDIA Python 라이브러리](https://python.langchain.com/docs/integrations/chat/nvidia_ai_endpoints/)를 호출하는 함수를 만들고 [`@weave.op`](/ko/products/wandb/weave/guides/tracking/ops)로 데코레이트하세요.
다음 예시에서는 두 함수를 Op로 래핑합니다. 이를 통해 RAG 앱의 검색 step과 같은 중간 단계가 앱의 동작에 어떤 영향을 주는지 확인할 수 있습니다.
```python lines {1,9,11,29,31,33} theme={"system"}
import weave
from langchain_nvidia_ai_endpoints import ChatNVIDIA
import requests, random
PROMPT="""Emulate the Pokedex from early Pokémon episodes. State the name of the Pokemon and then describe it.
Your tone is informative yet sassy, blending factual details with a touch of dry humor. Be concise, no more than 3 sentences. """
POKEMON = ['pikachu', 'charmander', 'squirtle', 'bulbasaur', 'jigglypuff', 'meowth', 'eevee']
client = ChatNVIDIA(model="mistralai/mixtral-8x7b-instruct-v0.1", temperature=0.7, max_tokens=100, top_p=1)
@weave.op
def get_pokemon_data(pokemon_name):
# RAG 앱의 검색 step처럼 애플리케이션 내의 한 단계입니다
url = f"https://pokeapi.co/api/v2/pokemon/{pokemon_name}"
response = requests.get(url)
if response.status_code == 200:
data = response.json()
name = data["name"]
types = [t["type"]["name"] for t in data["types"]]
species_url = data["species"]["url"]
species_response = requests.get(species_url)
evolved_from = "Unknown"
if species_response.status_code == 200:
species_data = species_response.json()
if species_data["evolves_from_species"]:
evolved_from = species_data["evolves_from_species"]["name"]
return {"name": name, "types": types, "evolved_from": evolved_from}
else:
return None
@weave.op
def pokedex(name: str, prompt: str) -> str:
# 다른 Op를 호출하는 루트 Op입니다
data = get_pokemon_data(name)
if not data: return "Error: Unable to fetch data"
messages=[
{"role": "system","content": prompt},
{"role": "user", "content": str(data)}
]
response = client.invoke(messages)
return response.content
weave.init('pokedex-nvidia')
# 특정 포켓몬의 데이터 조회
pokemon_data = pokedex(random.choice(POKEMON), PROMPT)
```
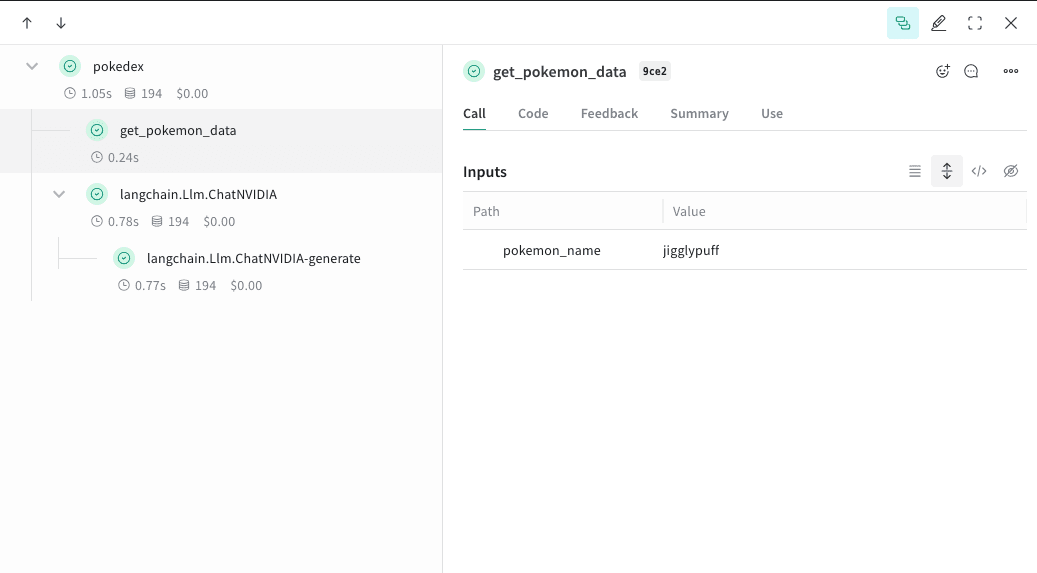
Weave로 이동한 후 UI에서 `get_pokemon_data`를 클릭하면 해당 단계의 입력과 출력을 확인할 수 있습니다.
```plaintext theme={"system"}
이 라이브러리는 Python 전용이므로 아직 TypeScript에서는 이 기능을 사용할 수 없습니다.
```
더 쉬운 실험을 위해 `Model` 만들기
구성 요소가 많으면 실험을 체계적으로 관리하기 어렵습니다. [`Model`](/ko/products/wandb/weave/guides/core-types/models) 클래스를 사용하면 system 프롬프트나 사용 중인 모델 등 앱의 실험 세부 정보를 캡처하고 정리할 수 있습니다. 이를 통해 앱의 여러 반복 버전을 체계적으로 정리하고 비교할 수 있습니다.
[`Model`](/ko/products/wandb/weave/guides/core-types/models)은 코드 버전을 관리하고 입력과 출력을 캡처할 뿐만 아니라, 애플리케이션의 동작을 제어하는 구조화된 매개변수도 캡처합니다. 따라서 어떤 매개변수가 가장 효과적이었는지 쉽게 찾을 수 있습니다. 또한 Weave Model은 `serve` 및 [`Evaluation`](/ko/products/wandb/weave/guides/core-types/evaluations)과 함께 사용할 수도 있습니다.
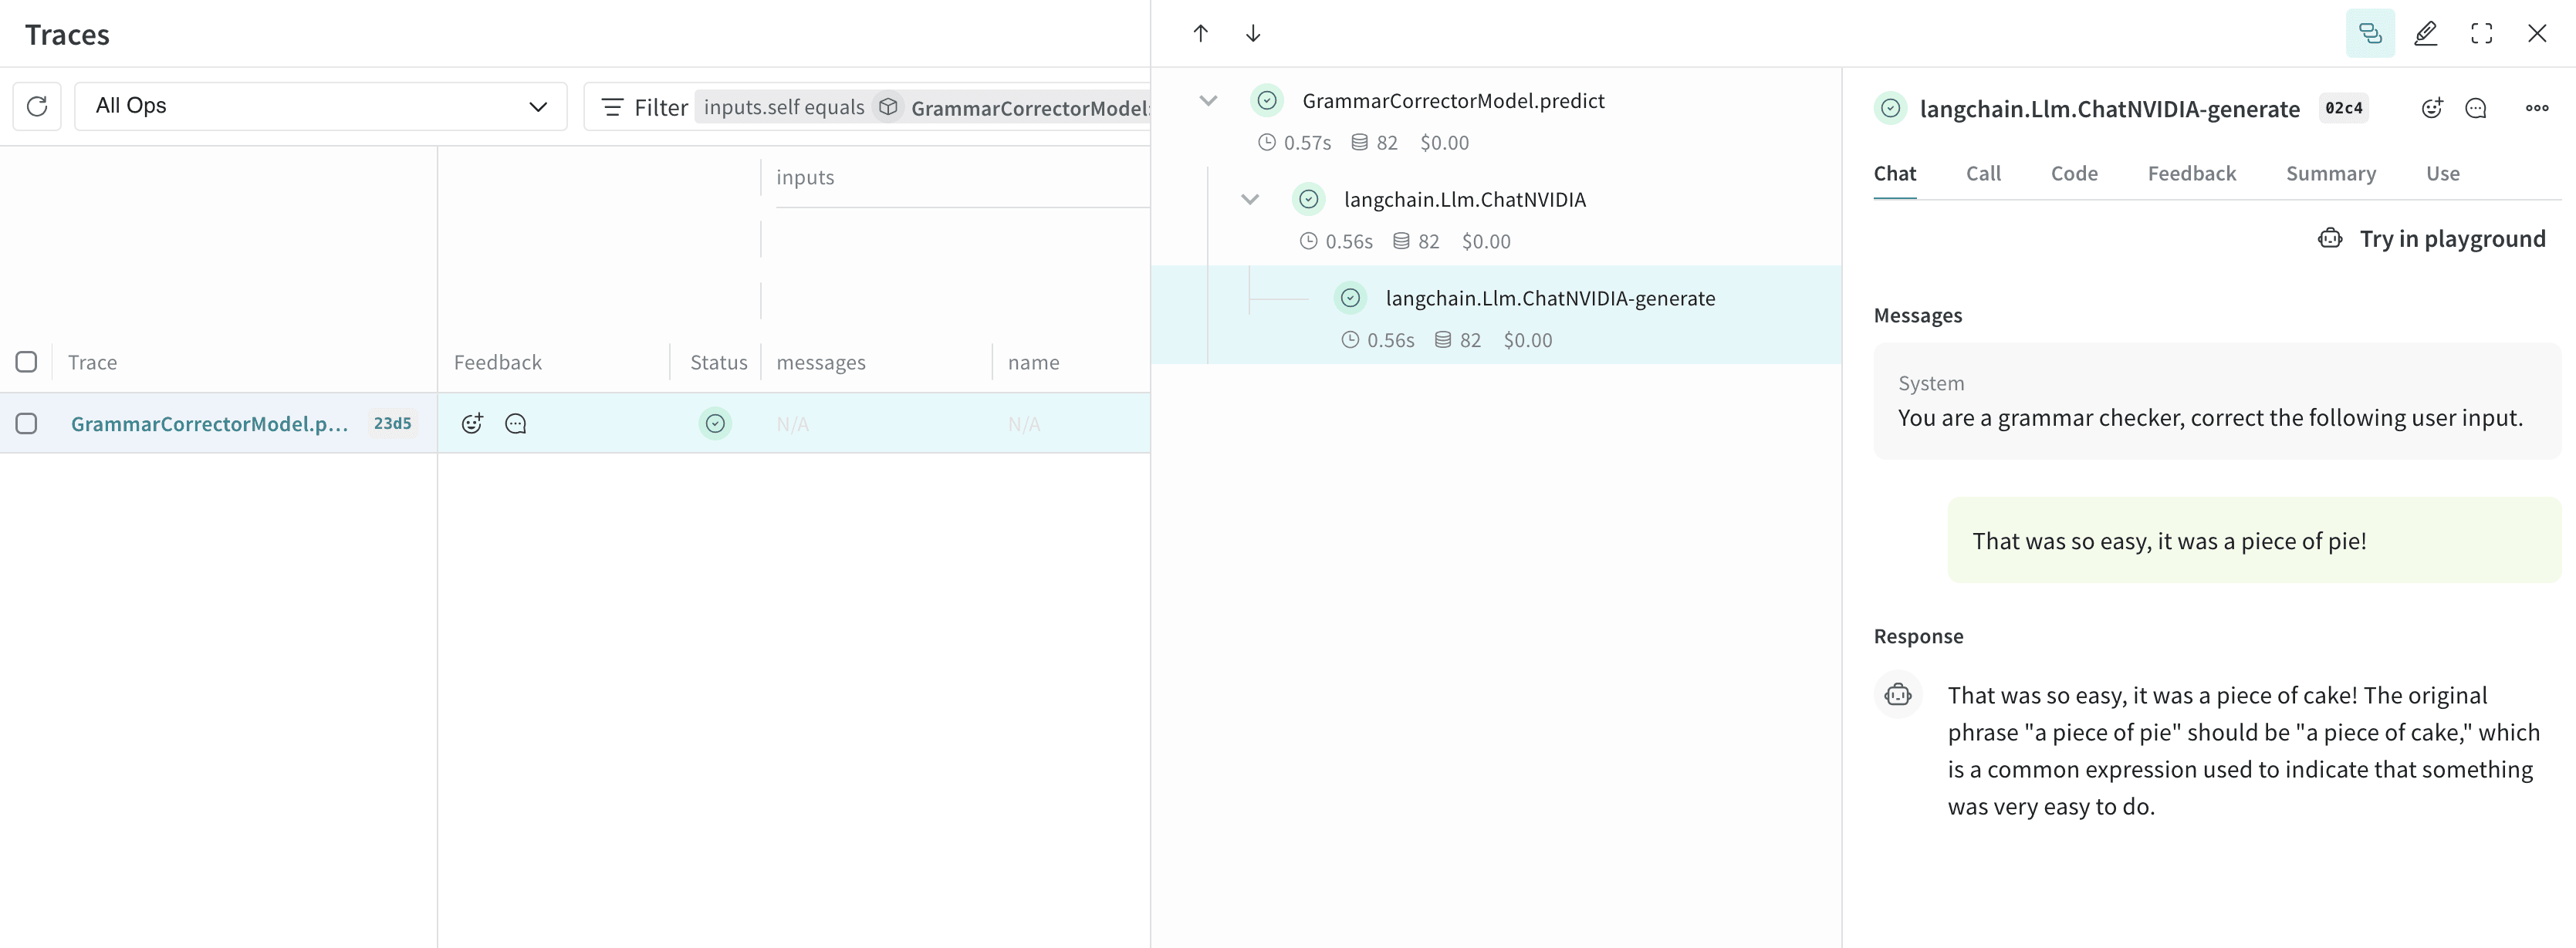
다음 예시에서는 `model`과 `system_message`를 바꿔 가며 실험할 수 있습니다. 둘 중 하나를 변경할 때마다 `GrammarCorrectorModel`의 새 \_버전\_이 생성됩니다.
```python lines theme={"system"}
import weave
from langchain_nvidia_ai_endpoints import ChatNVIDIA
weave.init('grammar-nvidia')
class GrammarCorrectorModel(weave.Model): # `weave.Model`로 변경
system_message: str
@weave.op()
def predict(self, user_input): # `predict`로 변경
client = ChatNVIDIA(model="mistralai/mixtral-8x7b-instruct-v0.1", temperature=0, max_tokens=100, top_p=1)
messages=[
{
"role": "system",
"content": self.system_message
},
{
"role": "user",
"content": user_input
}
]
response = client.invoke(messages)
return response.content
corrector = GrammarCorrectorModel(
system_message = "You are a grammar checker, correct the following user input.")
result = corrector.predict("That was so easy, it was a piece of pie!")
print(result)
```
```plaintext theme={"system"}
이 라이브러리는 Python 전용이므로 이 기능은 아직 TypeScript에서 사용할 수 없습니다.
```
사용 정보
다음은 ChatNVIDIA 인테그레이션에서 지원하는 기능을 설명합니다.
ChatNVIDIA 인테그레이션은 `invoke`, `stream` 및 각각의 비동기 버전을 지원하며, 도구 사용도 지원합니다.
ChatNVIDIA는 다양한 유형의 모델에서 사용하도록 설계되었으므로 함수 호출은 지원하지 않습니다.